Security for skills and MCP servers: what to assess before installing
Skills and MCP servers make AI agents more useful. A skill can guide a workflow; an MCP server can connect an agent to files, APIs, and other systems. The problem begins when we choose these extensions by looking only at what they promise to do, without asking what authority we are handing over with them.
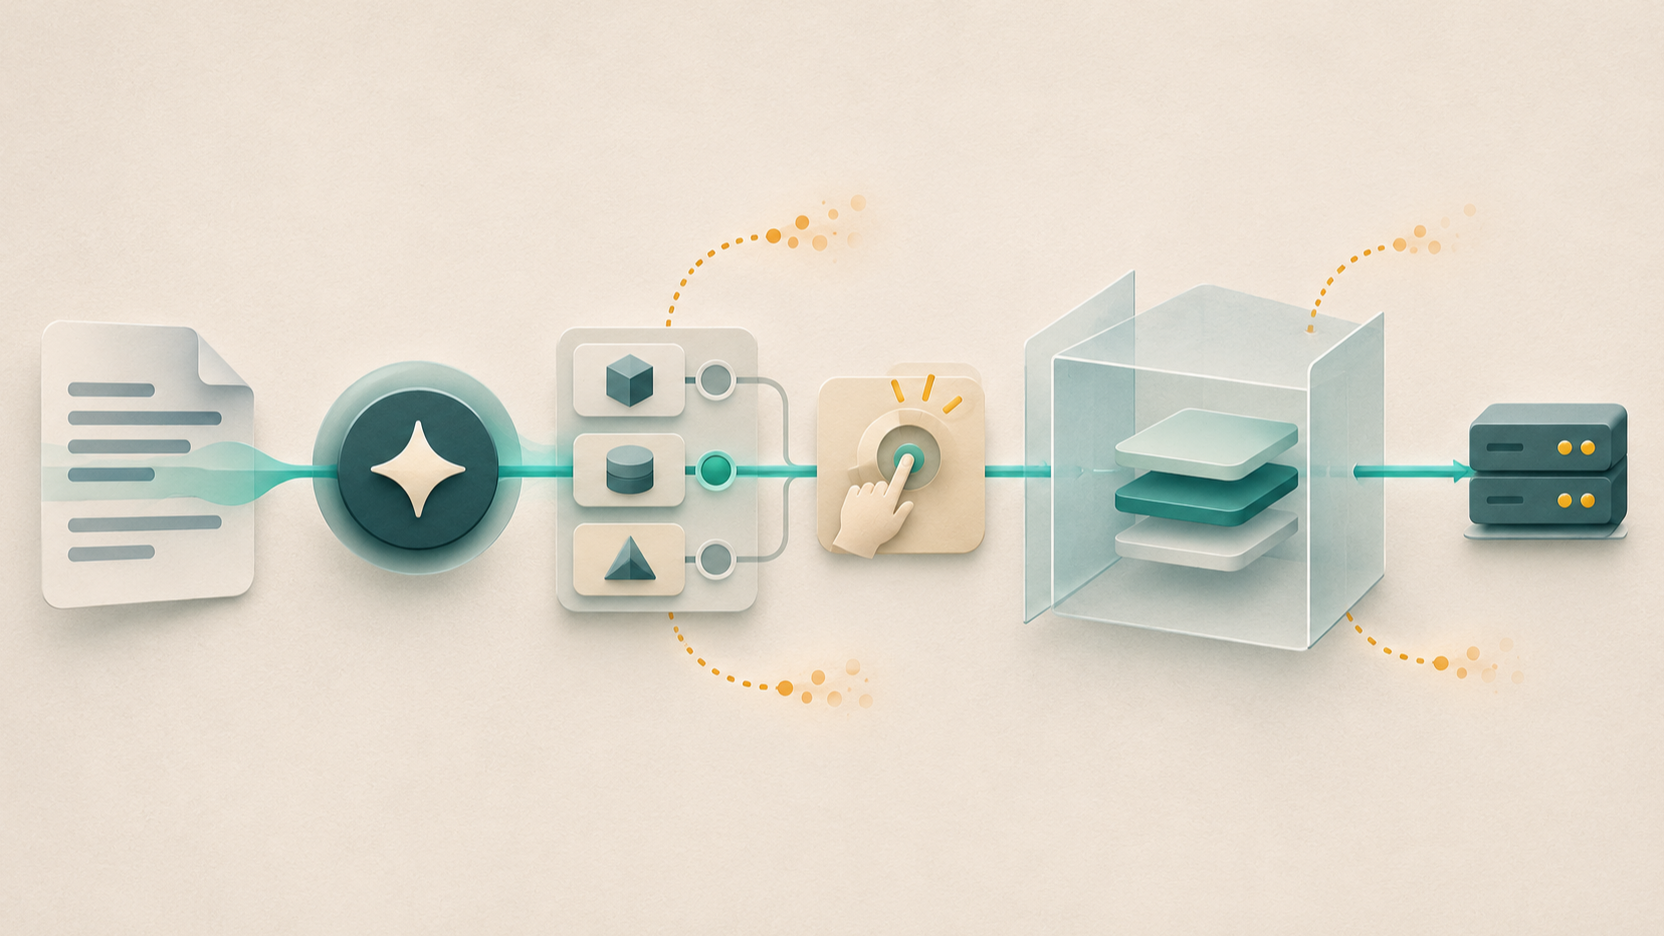
A well-written description is not a security boundary. To assess an extension, it helps to look at the whole chain: what content reaches the agent, which tools are available, who authorizes the call, and what effect it can have.
A skill and MCP are not the same thing
A skill is usually a package of instructions and, depending on the agent and format, may include scripts or supporting documentation. In Pi, for example, skills can be loaded from Markdown files and directories with supporting materials. What they can do depends on the tools the agent already has and on how the host interprets and executes those instructions. Pi skills documentation
MCP is a protocol for connecting clients to servers that expose capabilities, such as tools. The protocol describes how to discover and call a tool; by itself, it does not determine the process permissions or require a universal confirmation interface. The current MCP tools specification leaves the interaction model to each implementation and recommends that people be able to deny calls. This is a protocol recommendation, not a guarantee that every client will show the same confirmation. Clients implementing an earlier version may follow the 2025-11-25 specification.
In practice, a skill can guide an agent to use a tool, and an MCP server can provide it. To understand the risk, you need to consider both sides and the environment connecting them.
The risk lies in the action chain
Imagine an agent reading a repository or a web page. The content may contain malicious instructions disguised as documentation. This is a case of indirect prompt injection: external text influences the model’s behavior. The OWASP describes impacts that may include data exposure, unauthorized access to functions, or commands executed on connected systems.
Finding a malicious instruction does not mean a compromise has automatically occurred. The impact depends on what happens next: the agent must interpret the content as an instruction, have a relevant capability available, be able to use it with the existing authorization, and produce an effect. If one of these steps is blocked, the result may be limited to a bad response or a failed attempt.
So the useful question is not only, “Is this skill trustworthy?” Also ask, “If the agent follows an improper instruction, what can it do?”
What to check before adding one
1. Origin and maintenance. Check who publishes the skill or server, where the code comes from, when it was updated, and how changes are communicated. Prefer pinned versions or verifiable releases when the tool allows it. A familiar name or a high star count can provide context, but does not replace reviewing what will be installed.
2. What will run. Read the instructions, installation commands, scripts, and dependencies. A local MCP server runs with the identity and permissions granted by its host and the operating system; a sandbox and other restrictions may limit that access. The MCP security best practices recommend showing the full command and asking for consent before configuring a local server, as well as restricting access to files, the network, and other resources.
3. Access to data and credentials. Identify which files, environment variables, tokens, and accounts the extension can reach. Keep tokens out of the model’s context whenever possible, and limit credentials, in the host or code, to the operations required. If the integration supports scopes, restrict them to the service and actions needed for the task.
4. Available effects. Distinguish reading from writing, command execution, and external actions such as sending messages or changing resources in an account. If a task only needs to retrieve data, do not leave a deletion or publishing tool enabled. Disable network or file-system access when they are not needed.
5. Approval and isolation. For high-impact operations, people should be able to understand the specific action and refuse it. A generic or automatic confirmation loses its value. Use a sandbox and disposable directories to test untrusted content, and keep execution isolated from the environment that stores your credentials and important data.
6. Logging and revocation. Find out what logs the host and server provide and how to disconnect the integration or revoke its credentials. Logging availability and detail depend on the implementation. Record the requested action, authorization, and result when possible. If behavior or permissions change, revoke access and investigate before enabling it again.
MCP does not replace client and server controls
MCP defines communication; the client and server still need to implement appropriate controls. The current specification tells clients to treat tool annotations as untrusted unless they come from trusted servers. Metadata such as “read-only” describes an intent; it does not prove that the tool or connected system will prevent changes.
Do not rely only on a prompt telling the model to ignore malicious instructions. OWASP notes that it is unclear whether fail-safe methods for preventing prompt injection exist. Instructions, filters, and content separation can help, but limiting privileges and requiring human approval for higher-risk actions can reduce the possible impact.
A controlled test before trusting one
Before connecting a skill or MCP to your main environment, test it in an authorized and isolated environment with disposable data and accounts. Record the extension’s version or hash, the identity and scopes used, the call made, and the observed effect; also define how to clean up the test data.
Inventory the available tools and ask, for each one: does it read or change data? Can it run code? Can it access the network? Which identity and permissions does it use? What happens if the call receives unexpected parameters? Check authorization on the server and the effect on the connected system: testing parameters alone does not show that authorization is secure.
Then try removing every capability that is not essential. If the task still works without terminal, network, or write access, leave those permissions off. If a tool requires greater permissions, treat that as an explicit decision and assess whether the benefit outweighs the risk.
There is no checklist that makes every extension safe for every agent. Context matters: a skill limited to generating a draft has a different impact from an integration able to run commands or change an account. The most responsible choice is to understand what comes in, what can be called, and the limits of the damage before installing.